MBL Archive
Personal study archive for a two-year law degree: a Chrome-attached crawler pulls every reading and recording off Moodle, Claude Code subagents turn 50k WhatsApp messages into per-course digests, and one script regenerates course READMEs and a Notion workspace.
A private study archive for a two-year, part-time law programme, built to turn a year's worth of scattered material into something I can actually revise from: an LMS that had just been migrated to a new instance, a 50,000-message batch WhatsApp group, and lecture recordings that only stream inside the LMS player.
It's three pipelines that write into one folder tree per course, plus a generator that turns the tree into readable pages.
- Moodle archiver — I log in once in a normal Chrome window; the tool attaches over the DevTools protocol, saves the session, and mints a mobile web-service token from it, so the crawl runs headless afterwards and never sees a password.
core_course_get_contentsenumerates every section and activity; resources, folders, pages, forums, assignments and quizzes each get their own handler, and the dated "class recording" labels are paired with the Bunny.net HLS stream embedded in their HTML. A manifest keyed by content id makes re-runs idempotent. Recordings are transcoded withhevc_videotoolboxand copied into the Google Drive app's folder, and only count as done once Drive has assigned the file a cloud id. - WhatsApp digest — the iOS export is CRLF-delimited with bare newlines inside multi-line messages, which a naive parser silently drops; the parser splits on CRLF, matches headers with DOTALL, and checks its count against the export. Every sender is replaced by a stable label before anything else touches the text. A keyword-and-calendar pass tags messages to courses; the ~14k messages that carry links, documents, exam keywords or questions are classified by Claude Code subagents working through exported chunk files, and the results are imported back by message id. Timetable screenshots are OCR'd with Apple Vision so a photographed circular counts as a notice.
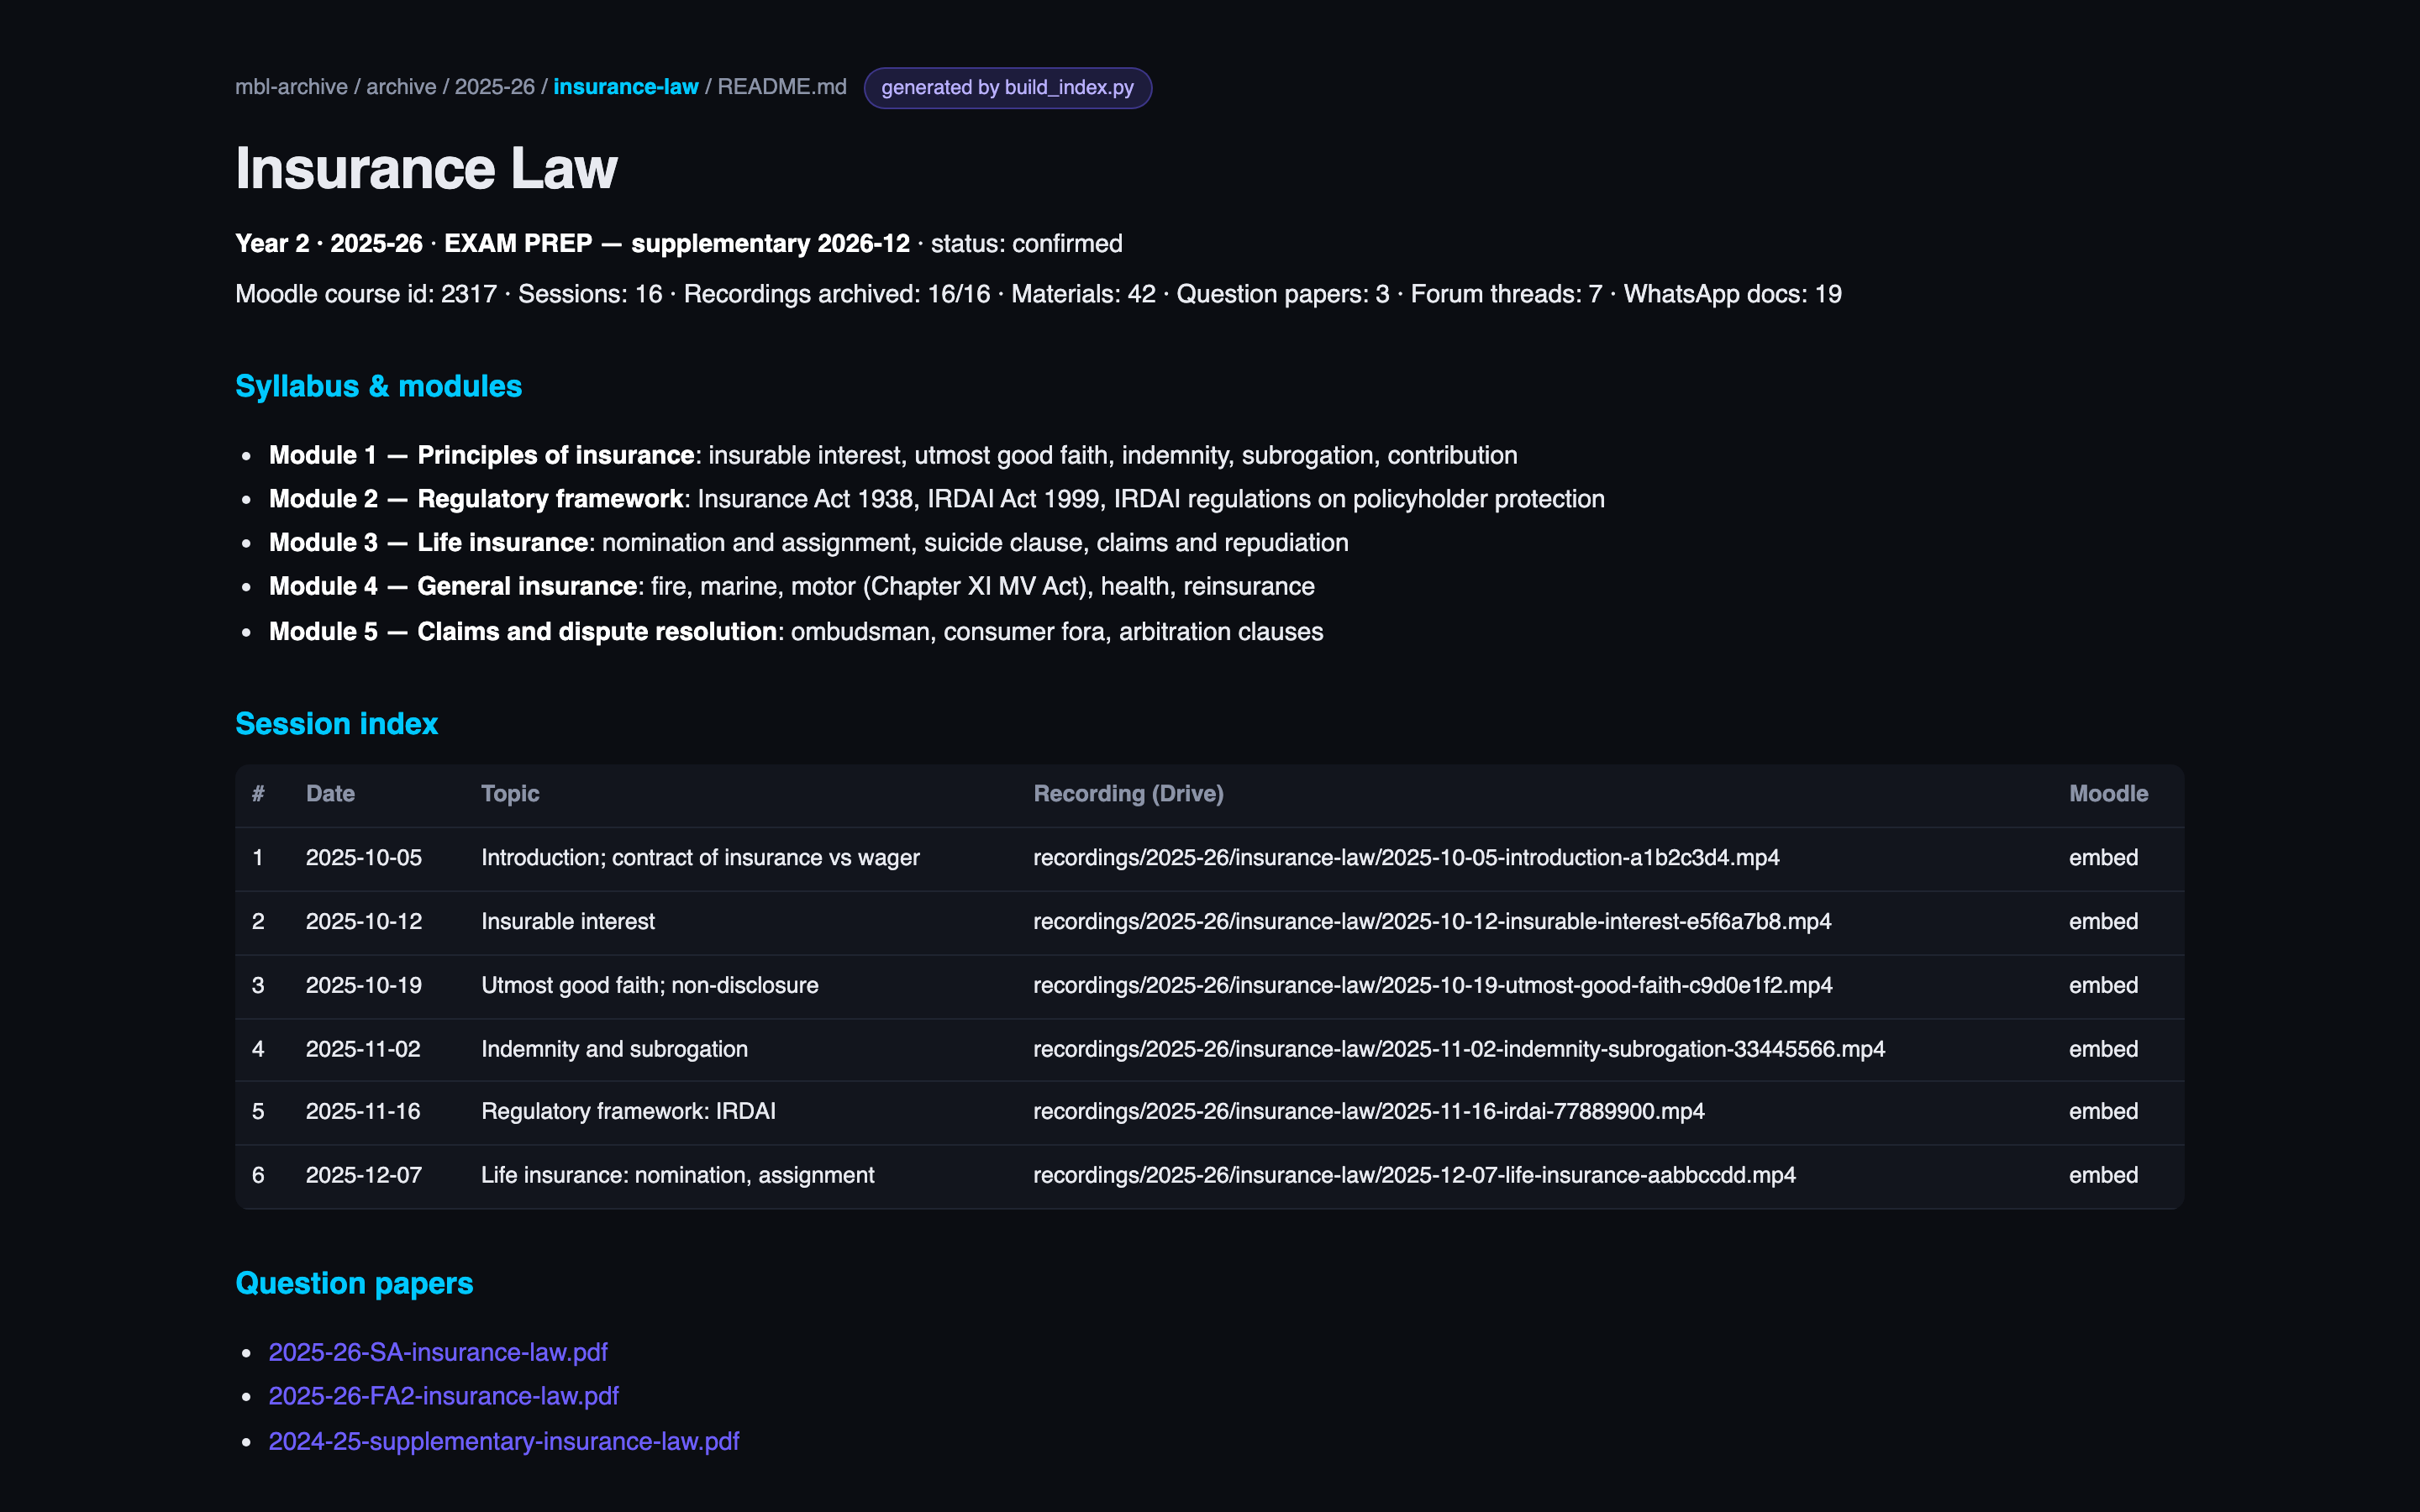
- Knowledge pages — one generator renders a README per course (syllabus, session index, question papers, digest takeaways, an exam-prep checklist) and a root page with the course matrix, preserving any hand-written block between markers. The same data is mirrored into Notion as one page per course.
The repository is private by design — course PDFs belong to the university and the chat belongs to a hundred classmates — so the public part is the tooling and this page. A pre-commit hook runs gitleaks plus a grep for phone numbers and email addresses; browser profiles, tokens, raw exports and the sender map live in ignored directories.
Stack — Python 3.11 · Playwright (CDP) · httpx · ffmpeg (VideoToolbox) · Google Drive for Desktop · Claude Code subagents · Apple Vision via ocrmac · Notion MCP